RAG Pipeline & Chatbot
Turn a knowledge base into grounded answers, with relevant context retrieved before every response.
The problem
Answers buried in scattered documentation are hard to find. A general-purpose chatbot may answer without reliable business context.
The solution
The workflow combines semantic retrieval with a language model, using source material to ground an answer rather than relying on model memory.
How it works
- 1
Pick up new documents
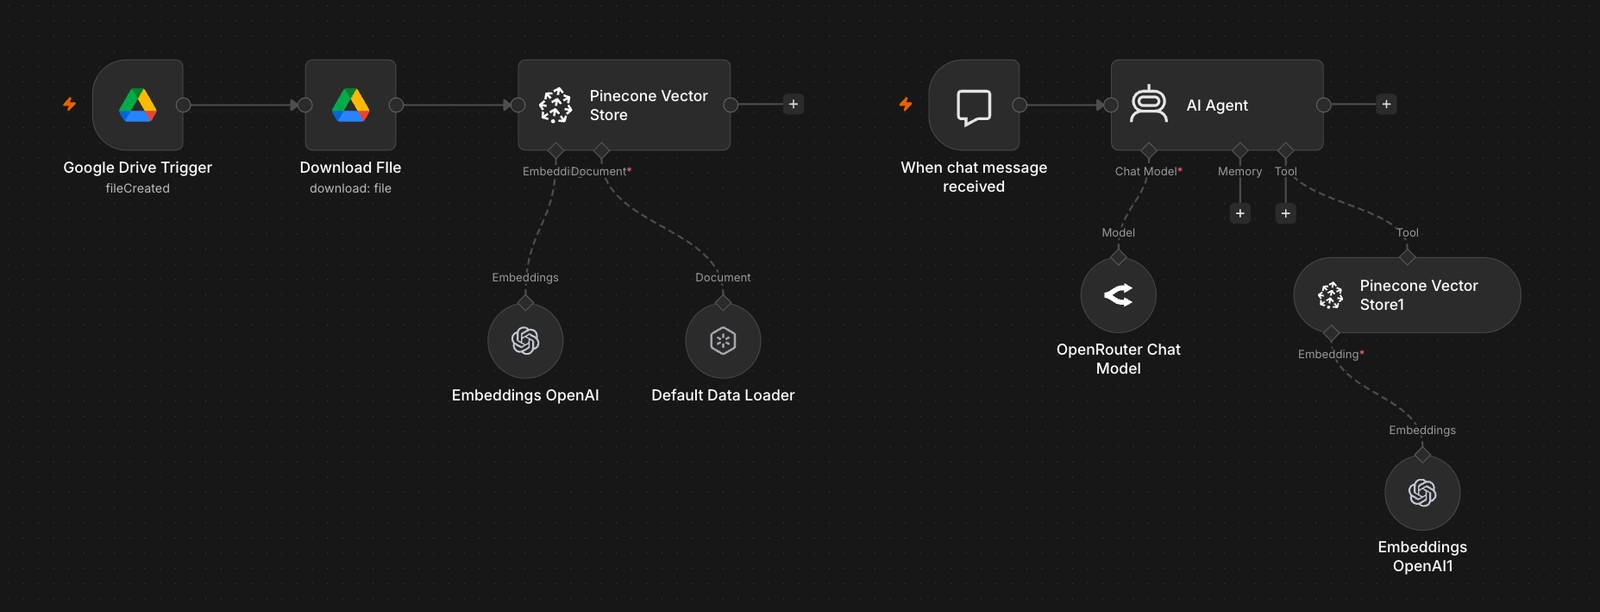
A Google Drive trigger fires when a file is added to the knowledge base folder, and the file is downloaded.
- 2
Store them in Pinecone
A data loader splits the document into passages, OpenAI embeddings turn each one into a vector, and Pinecone stores them for search.
- 3
Receive a question
A chat trigger starts the second flow whenever someone sends a message.
- 4
Answer from the documents
An AI agent on an OpenRouter chat model searches Pinecone for the matching passages and answers from them, not from memory.